
Models
The Models page (Settings cog → Models) is your facility's model catalog. "Turn models on or off for this account. All models are enabled by default. Individual keys and agents can be restricted further."
At the top of the page, the Automatically enable new models switch decides what happens when the catalog grows: "When a new model is added to the catalogue, turn it on for this account automatically. Turn this off to review new models yourself before they can be used."
For the live price of every model, see the Model Catalog, and for how models compare on capability and value, see the Model Rankings.
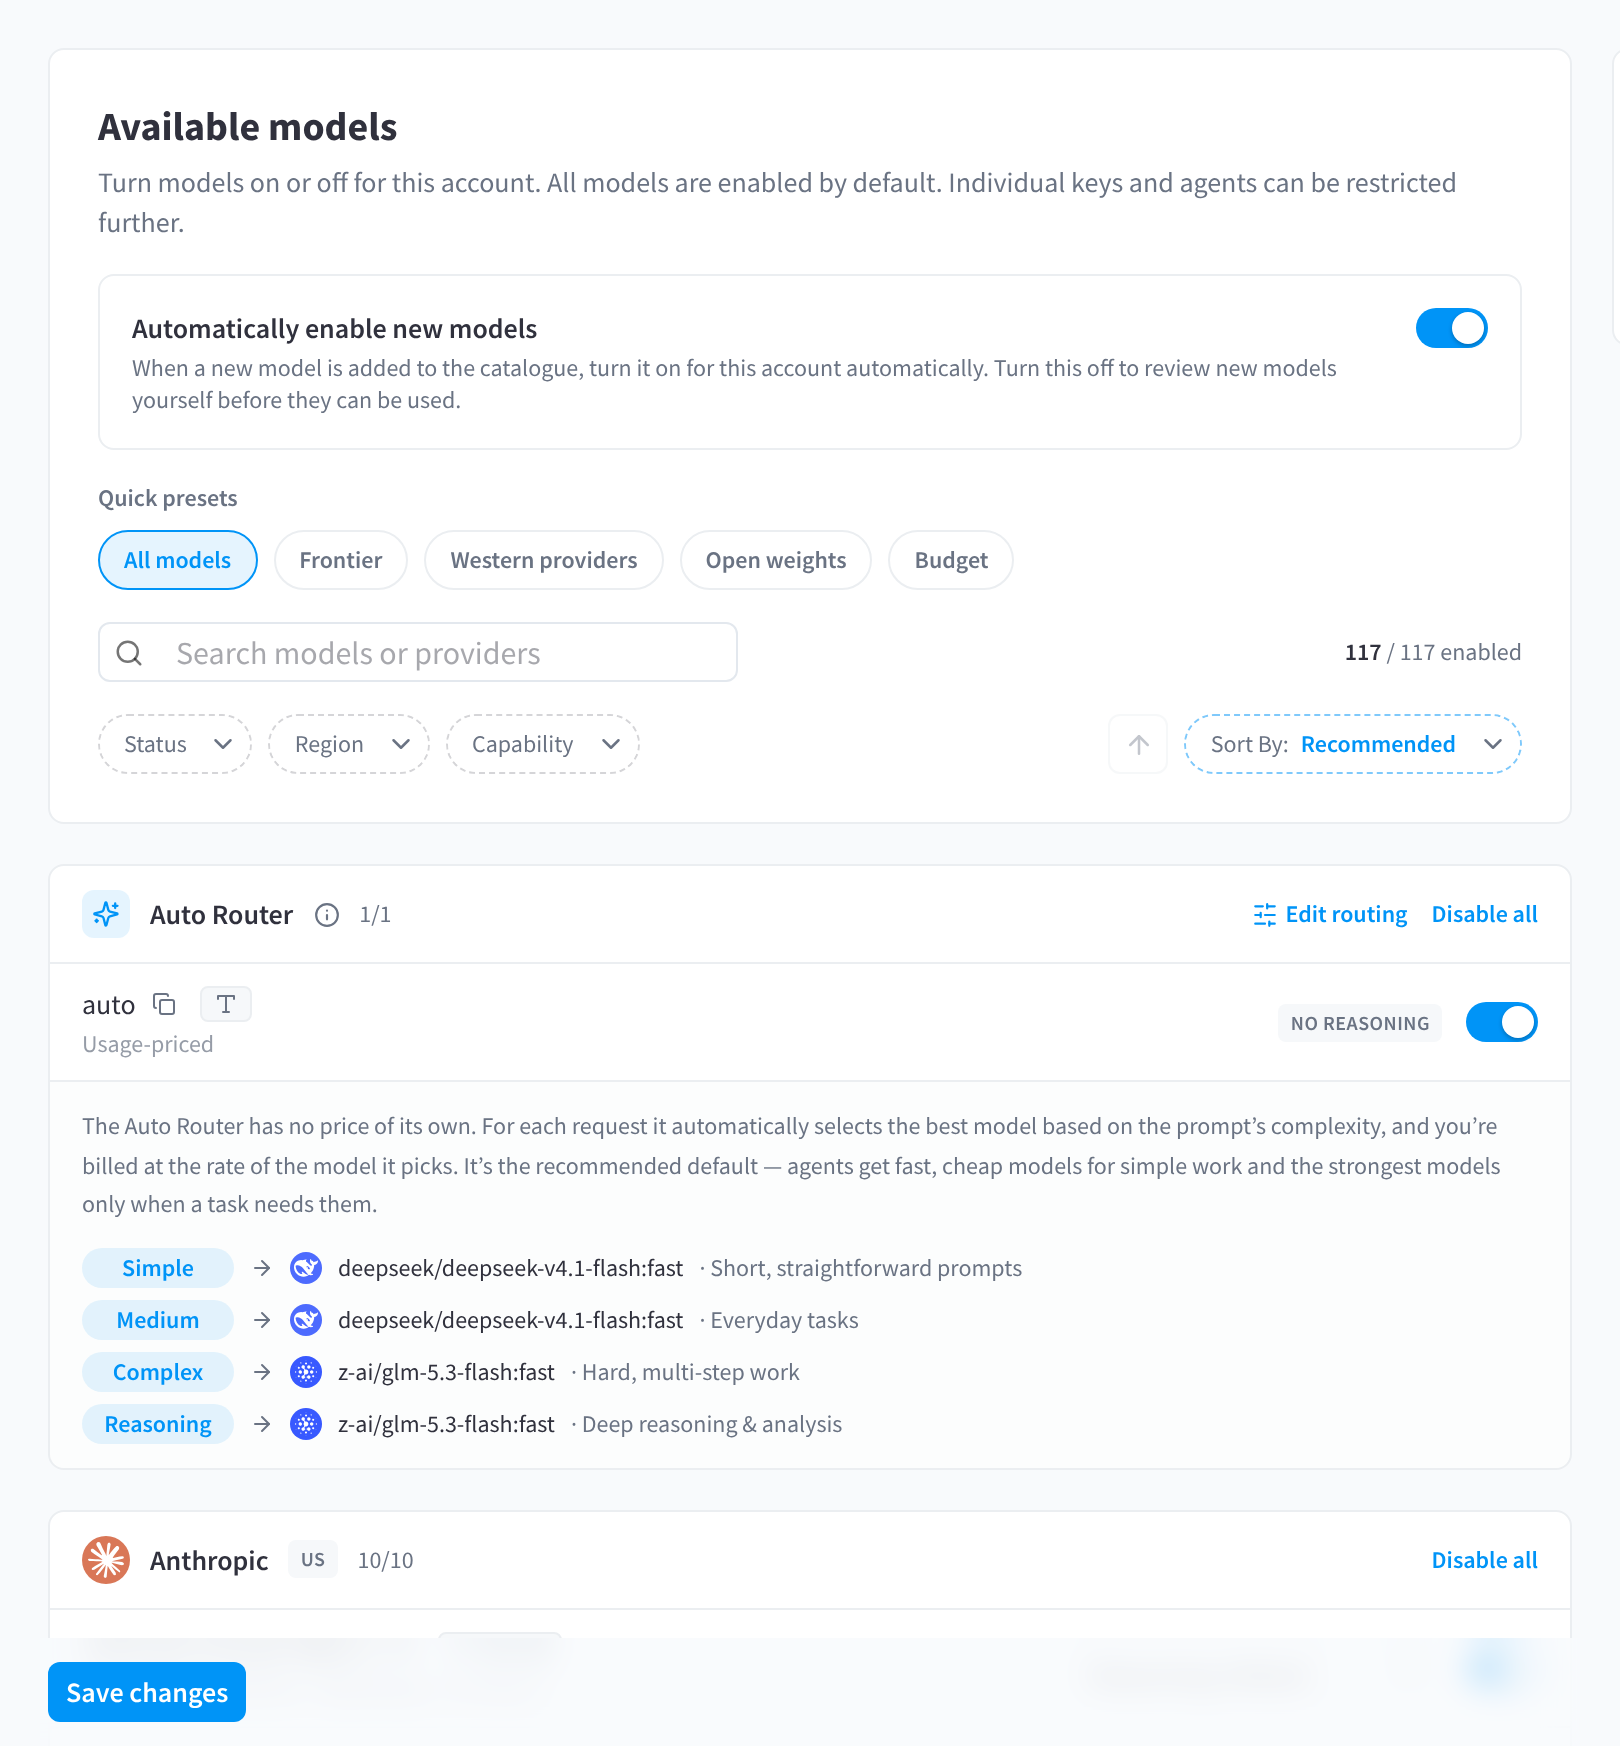
Figure 1: Available models: Automatically enable new models, quick presets, filters and the Auto Router card at the top of the list
The model list
Models are grouped by provider, each group showing a region badge (e.g. US) and an enabled count (e.g. 7/7); the list header shows the overall count (e.g. 117 / 117 enabled). Each model row shows:
- The model ID (e.g.
anthropic/claude-sonnet-4-5) - A Copy model ID button next to the ID
- Context window size (e.g. 200K context, 1M context)
- Pricing per million tokens, input and output separately (e.g. $3.15 in · $15.75 out / 1M tokens)
- Capability icons for what the model accepts: text, image, audio and PDF (hover an icon for its meaning, e.g. "Supports image input")
- A reasoning setting (e.g. Reasoning: Default), or a No reasoning badge for models that take no reasoning setting
- An enable/disable toggle
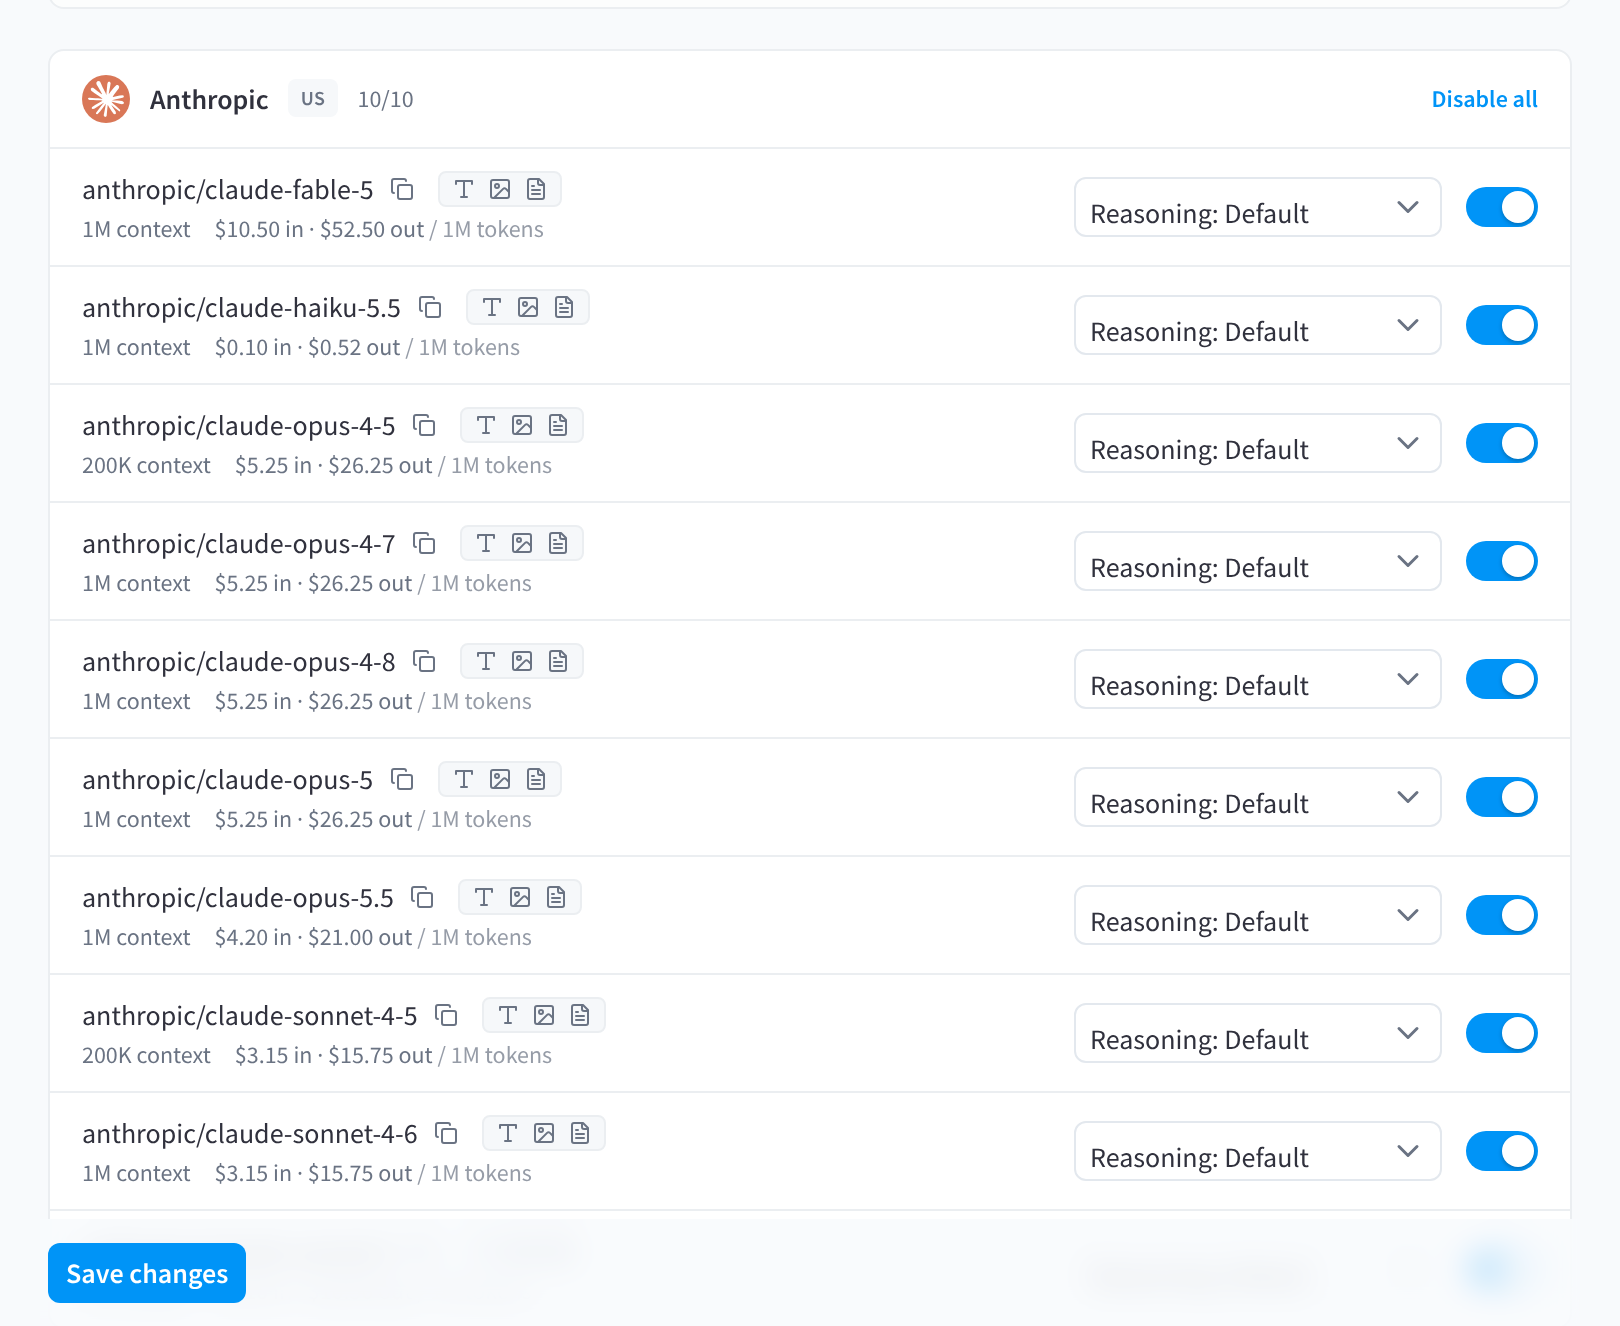
Figure 2: A provider group with each model's context size, pricing, reasoning setting and toggle
Toggle models on or off, then click Save changes. "At least one model must stay enabled." Each provider group has a Disable all / Enable all shortcut.
Disabling a model here blocks it for the whole facility — every API key and connected service. To narrow the list for just one key or service instead, use its Restrict models option (see API keys and Connected Services).
Reasoning setting
Each reasoning-capable model has a reasoning setting: the reasoning effort applied when a client does not request one. It is useful for tools that cannot set reasoning effort themselves; a client that sends its own level still wins.
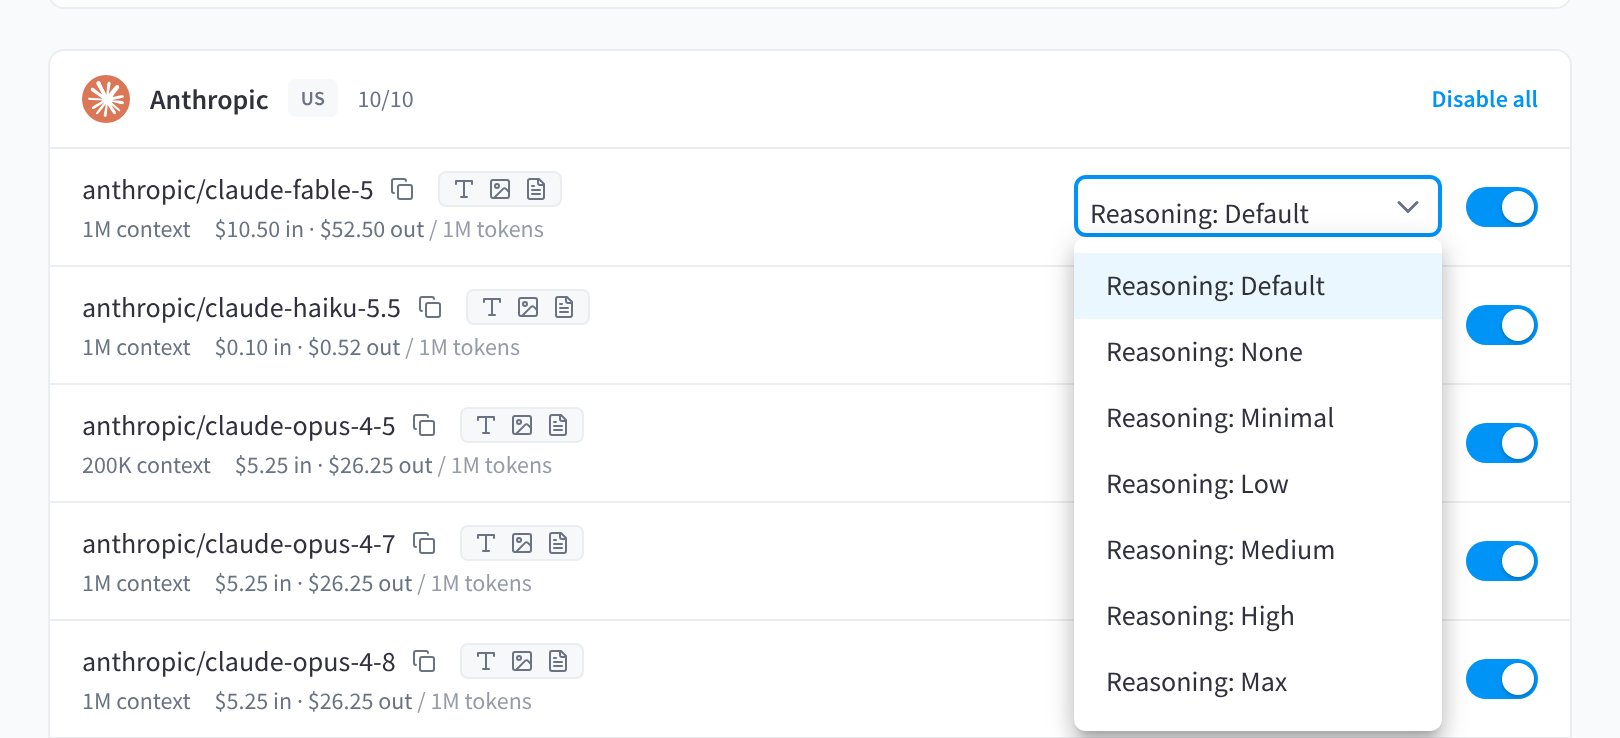
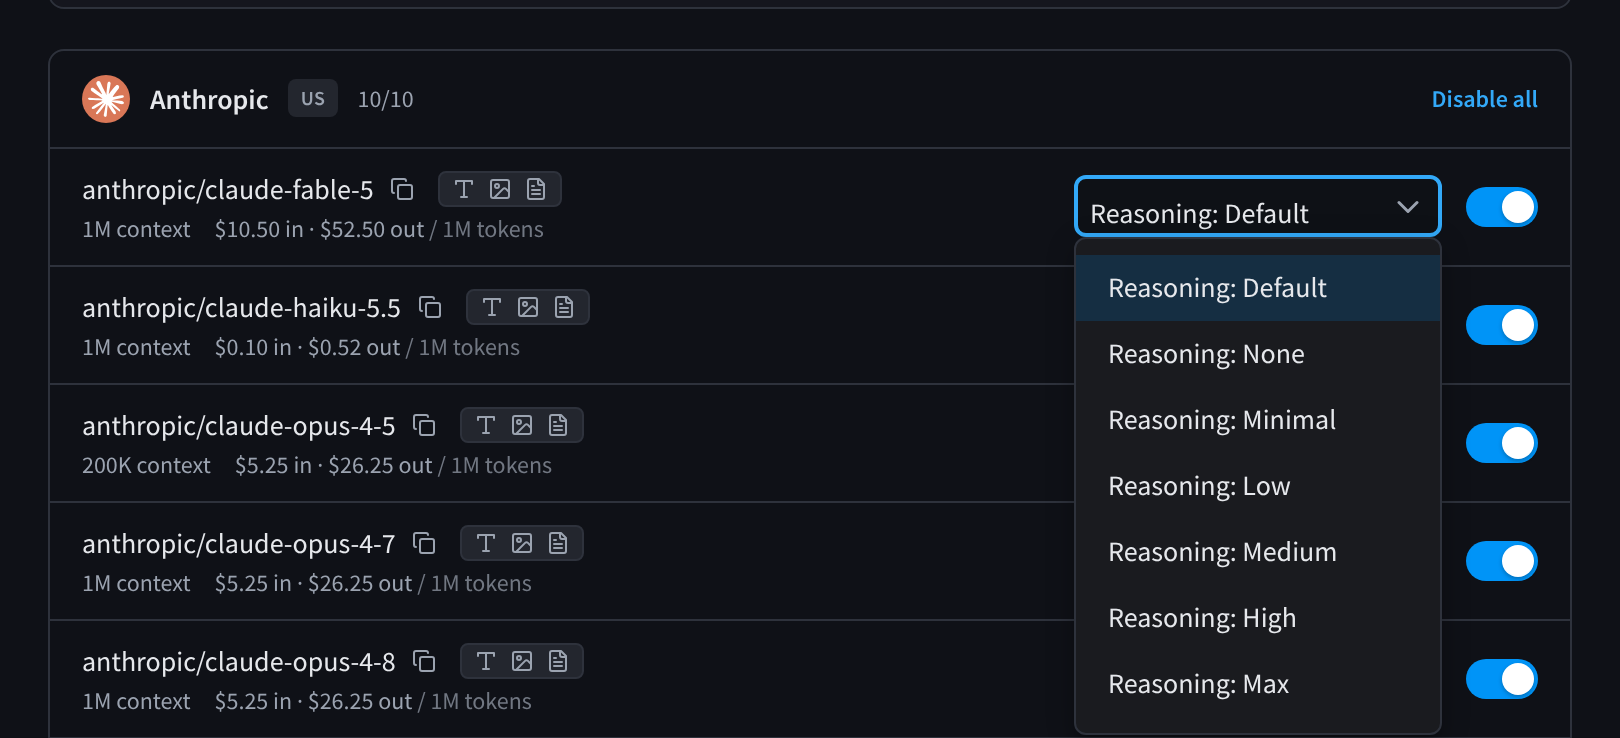
Figure 3: A model's reasoning setting open, showing Reasoning: Default and the effort levels
- Reasoning: Default leaves the provider's default in place.
- None, Minimal, Low, Medium, High and Max set the effort level used when a request does not include one. Some providers accept only certain levels.
- The setting can't be changed while the model is turned off.
- Models that do not accept a reasoning setting show No reasoning instead: "This model does not accept a reasoning setting, so no default can be configured for it."
Click Save changes to apply.
Quick presets
Presets apply a curated selection in one click (then Save changes to apply):
| Preset | Selection |
|---|---|
| All models | "Enable every available model." |
| Frontier | "Flagship models from Western labs (OpenAI, Anthropic, Google, xAI) plus the Auto Router." |
| Western providers | "Exclude models from Chinese providers (data-sovereignty friendly)." |
| Open weights | "Only models with openly available weights (Llama, Mistral, Qwen, DeepSeek…)." |
| Budget | "Low-cost models — input price at or below $1.00 per million tokens." |
Search, filters, and sorting
- Search matches model and provider names ("Search models or providers").
- Status — Any / Enabled / Disabled.
- Region — United States / Europe / China.
- Capability — Vision (image input), Audio (input or output), PDF input, Reasoning.
- Sort By — Recommended / Name / Price / Context size, ascending or descending.
If nothing matches you'll see "No models match your filters." with a Clear filters action.
The Auto Router (auto)
The Auto Router sits at the top of the list as the model ID auto, marked "Usage-priced":
"The Auto Router has no price of its own. For each request it automatically selects the best model based on the prompt's complexity, and you're billed at the rate of the model it picks. It's the recommended default — agents get fast, cheap models for simple work and the strongest models only when a task needs them."
Its info hint sums it up: "The Auto Router picks the best model for each request based on complexity. Callers use the single model "auto"; you decide which model handles each tier."
The card shows the current routing — which model handles each complexity tier:
| Tier | Handles |
|---|---|
| Simple | Short, straightforward prompts |
| Medium | Everyday tasks |
| Complex | Hard, multi-step work |
| Reasoning | Deep reasoning & analysis |
The current tier targets, with their prices, are published on the model catalog page.
In Activity and Logs, requests sent to auto show the model that actually served them; the request detail drawer records auto as the Requested model. This is expected — it's how you see what the router chose.
Editing the routing
Click Edit routing on the Auto Router card to customise the tier map for your facility:
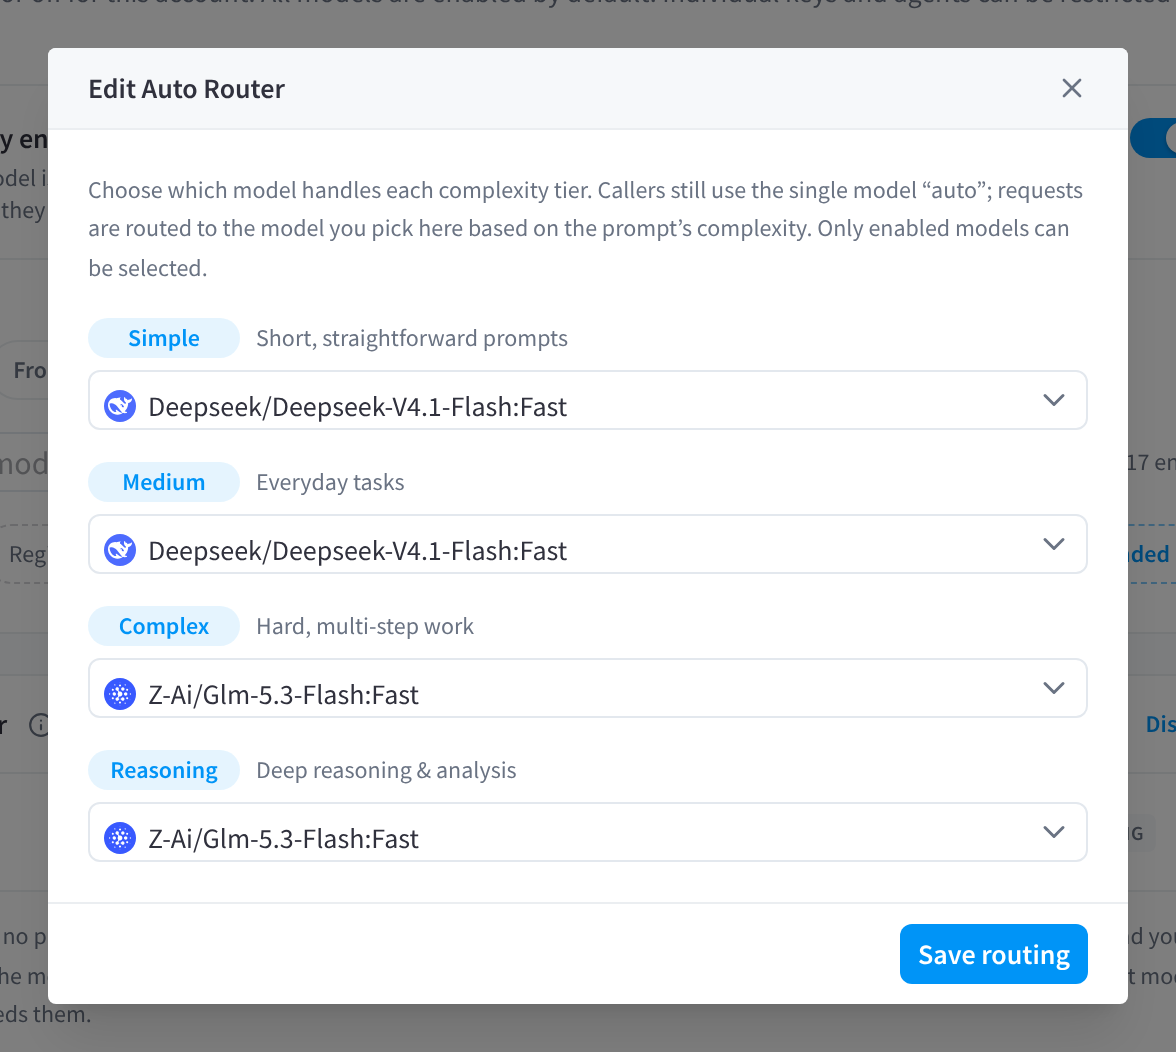
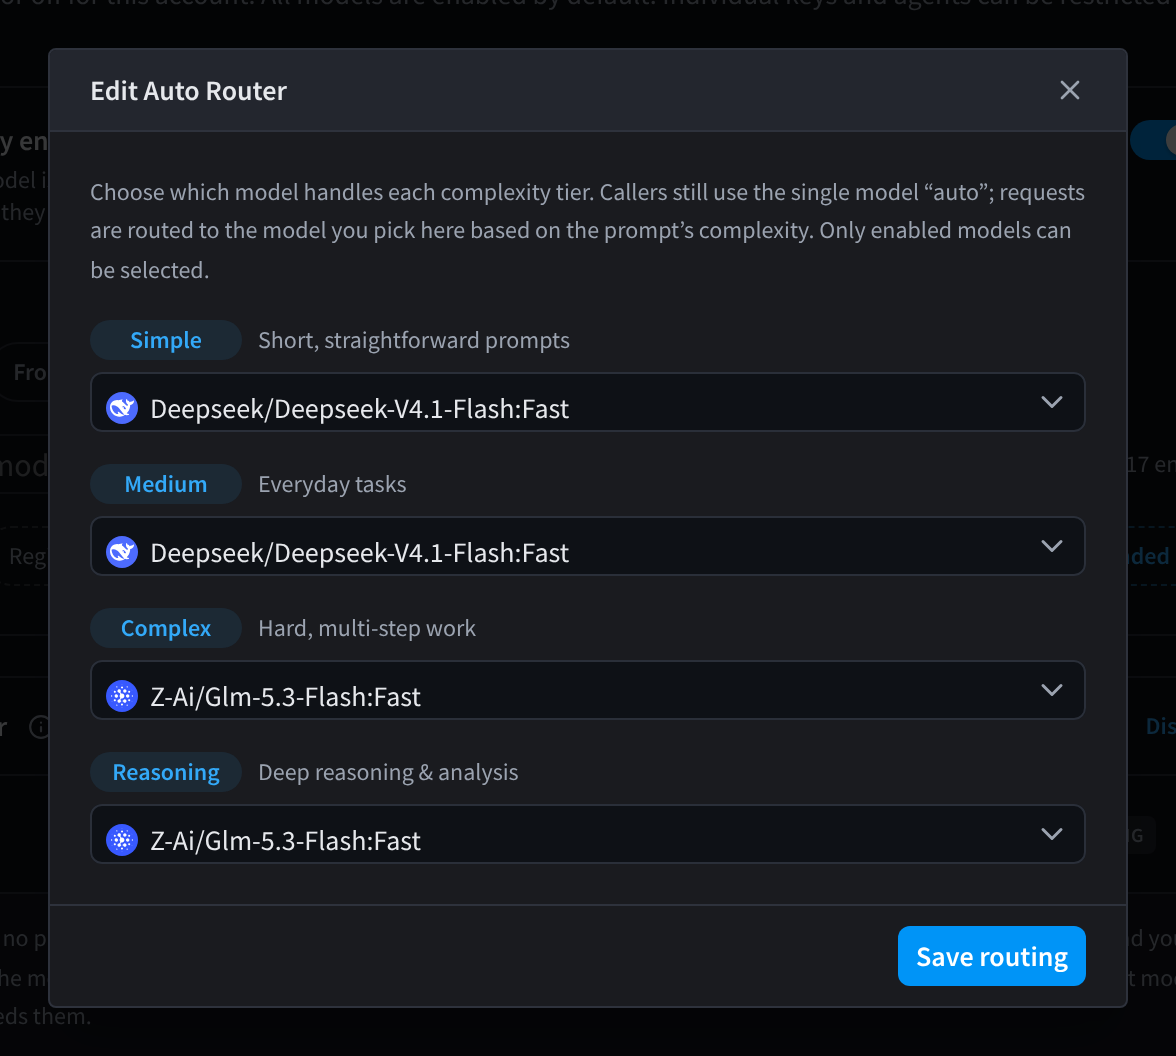
Figure 4: The Edit Auto Router dialog: one model for each complexity tier
"Choose which model handles each complexity tier. Callers still use the single model "auto"; requests are routed to the model you pick here based on the prompt's complexity. Only enabled models can be selected."
Pick a model for every tier ("Pick a model for every tier to save."), then Save routing. Reset to default returns your facility to the standard routing.
If your facility restricts the enabled-model list, keep the router's target models enabled — a routed request needs its resolved model to be available.
Missing a model?
The side card on the Models page: "Want to see a model added? Raise a support request and we'll add it if it's generally available." Use the Raise a support request link.